Data Engineering
104 articles tagged with "Data Engineering"
Stateful Stream Aggregations: Core Concepts
Keys, windows, watermarks, triggers, and checkpoints for robust stateful stream aggregations in Spark and similar engines.
Airflow max_active_runs vs Pools
Serialize DAG runs with max_active_runs and throttle shared-resource tasks with pools, using both for correctness and capacity.
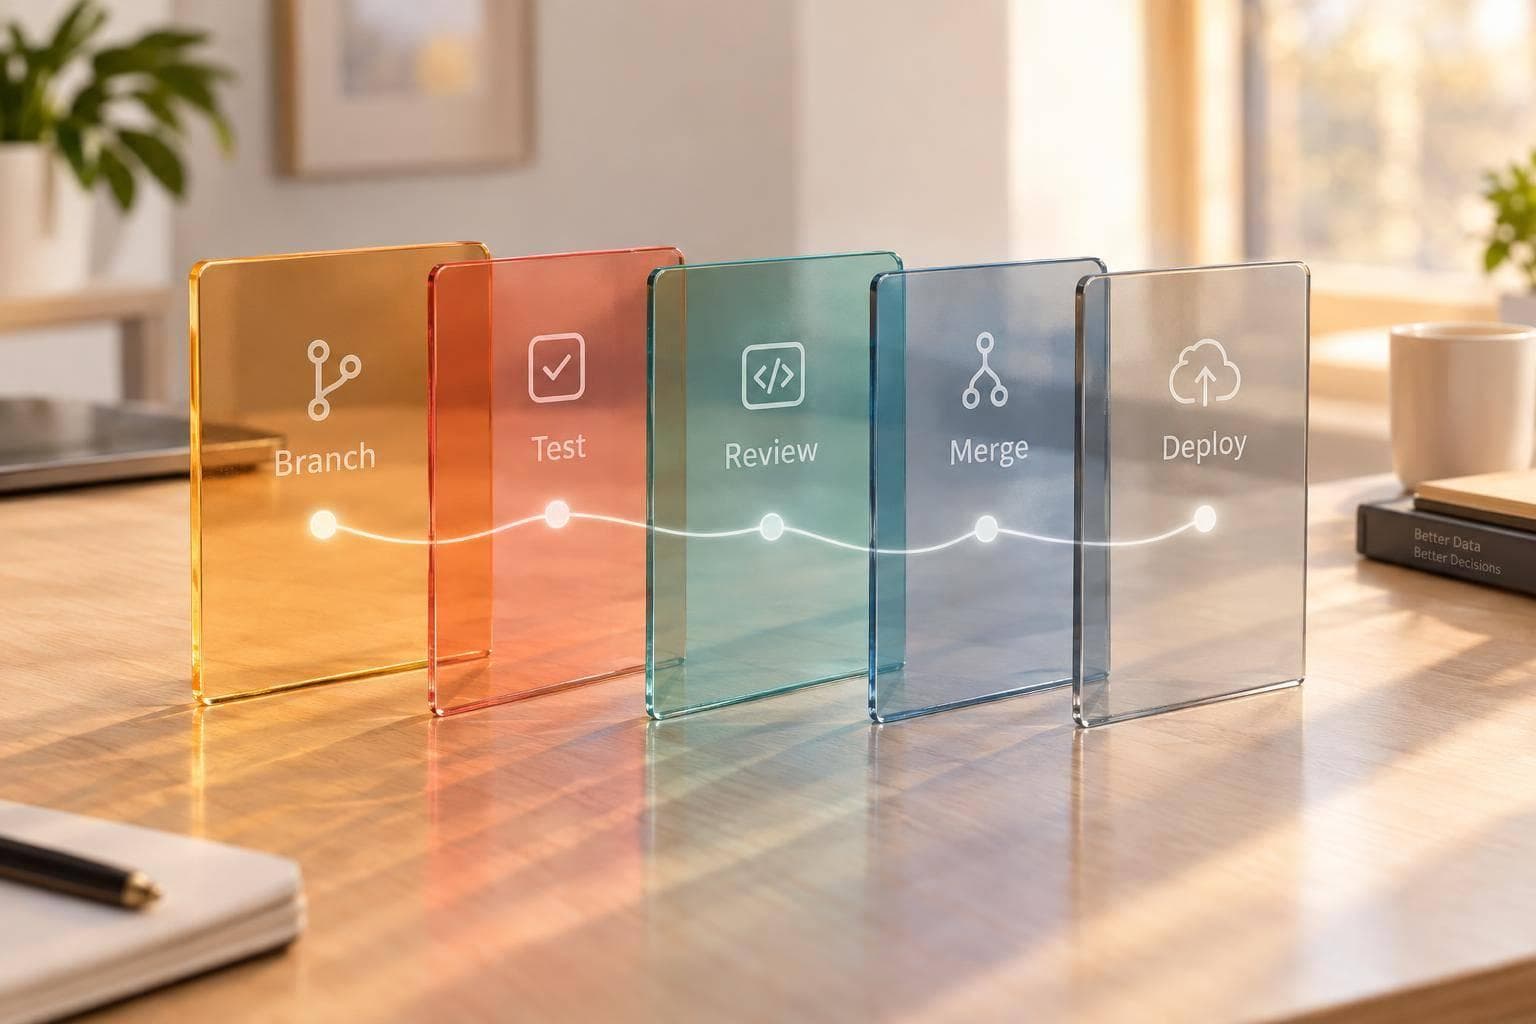
Version Control Basics for dbt Projects
Branch, test, review, merge, and deploy dbt changes with focused commits, CI validation, protected branches, and rollback plans.
Modern Data Stack 2026: Tools, Trends, Roadmap
Build a reliable data stack by prioritizing batch pipelines, clear ownership, and a budget before adding streaming or AI.
White-Label Embedded Analytics: Guide 2026
How to build secure, branded embedded analytics with tenant isolation, scoped embeds, exports, and staged rollout.
Introduction to Stream Processing Frameworks
Compare Flink, Kafka Streams, Spark, and Beam; test correctness, latency, recovery, and cost before choosing a streaming framework.
Provisioned Concurrency vs On-Demand: Latency Tradeoffs
Measure P95/P99 before paying for provisioned concurrency — choose on‑demand or provisioned to balance tail latency, cost, and spikes.
Data Engineer Certs and Salary: 2026 Guide
Certifications can open screens, but salary follows role scope, production ownership, and measurable impact.
How AWS IoT Core Processes IoT Event Streams
Explains how IoT Core ingests, filters, and routes device events, plus guidance on scaling, replay, and reliability.
Databricks Warehouse HA: 7 Design Patterns
Seven Databricks warehouse HA patterns to meet RTO/RPO: scaling, AZ resilience, failover, retries, stateless compute, standbys, isolation.
Airflow DAGs: Core Concepts and Task Design
Design Airflow DAGs for safe retries and idempotent publishing: task boundaries, sensors, schedules, timeouts, and testing.
Fraud Detection with Streaming Data: Use Cases
Use streaming events plus historical context to detect fraud across banking, e‑commerce, insurance, and telecom—making fast, accurate risk decisions.