Blog
Stateful Stream Aggregations: Core Concepts
Keys, windows, watermarks, triggers, and checkpoints for robust stateful stream aggregations in Spark and similar engines.
Airflow max_active_runs vs Pools
Serialize DAG runs with max_active_runs and throttle shared-resource tasks with pools, using both for correctness and capacity.
Snowflake Tutorial
Learn Snowflake step by step with guided lessons on SQL, data loading, warehouses, sharing, and performance basics.
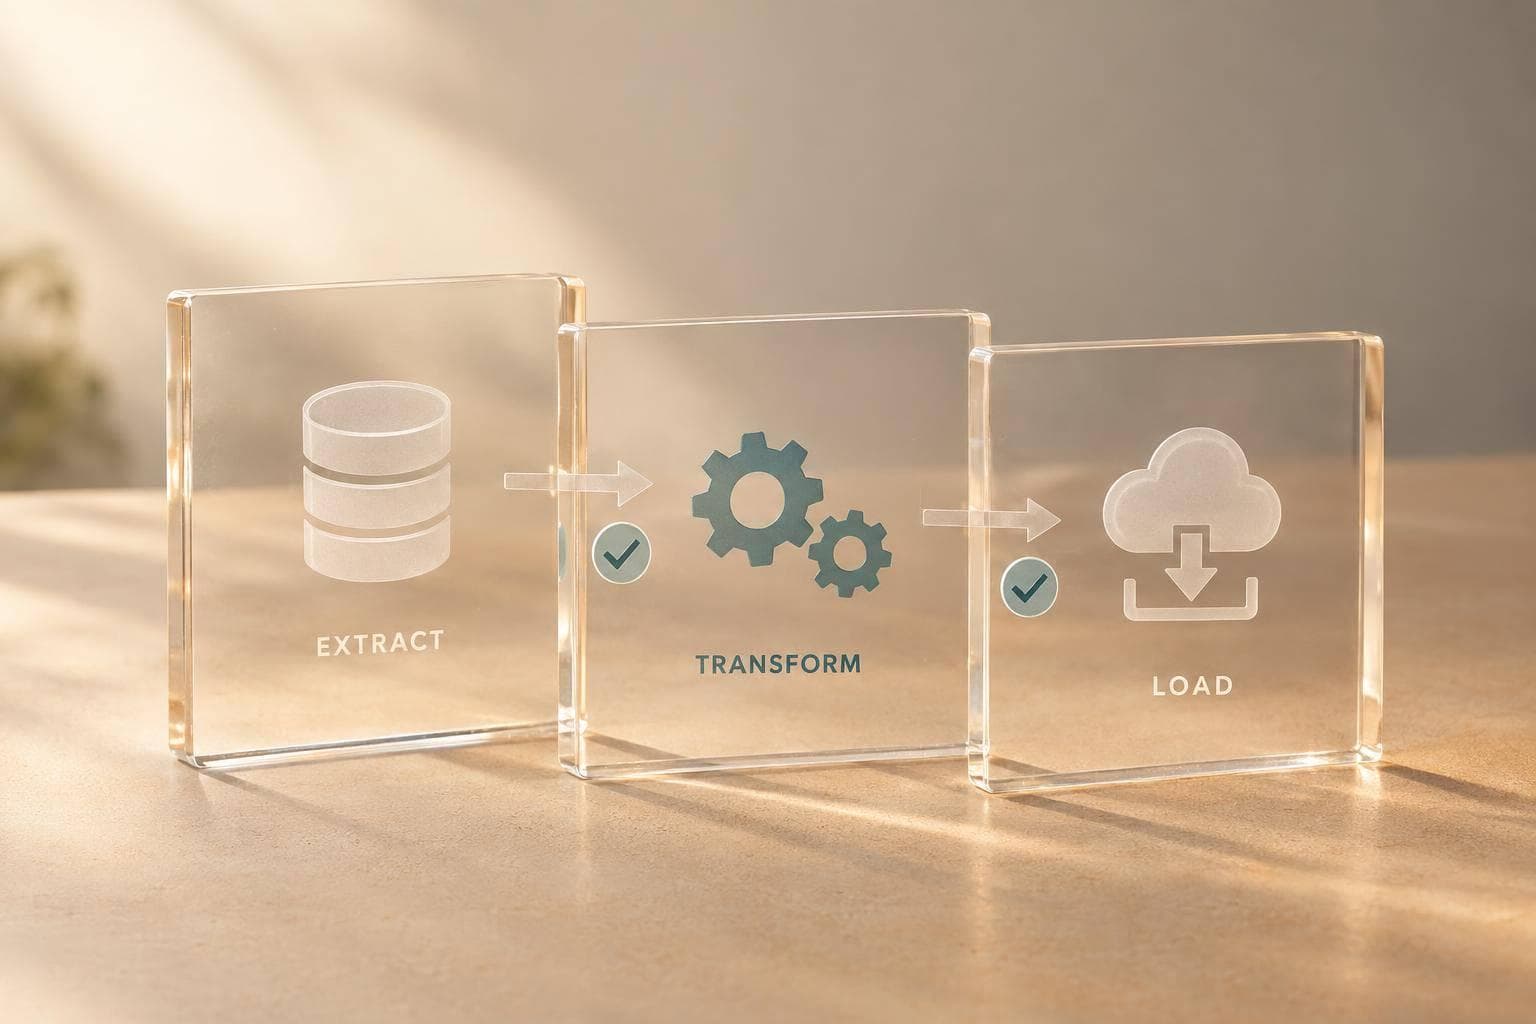
ETL Process
Map and understand your ETL process in minutes with tailored workflow steps, examples, quality checks, and best-practice guidance.
Version Control Basics for dbt Projects
Branch, test, review, merge, and deploy dbt changes with focused commits, CI validation, protected branches, and rollback plans.
Data Modeling Tutorial
Learn data modeling step by step with guided examples for beginners to advanced users, tailored to real business use cases.
Modern Data Stack 2026: Tools, Trends, Roadmap
Build a reliable data stack by prioritizing batch pipelines, clear ownership, and a budget before adding streaming or AI.
Data Engineering Learning Path
Build a personalized data engineering learning path with step-by-step modules, time estimates, projects, and job-ready study guidance.
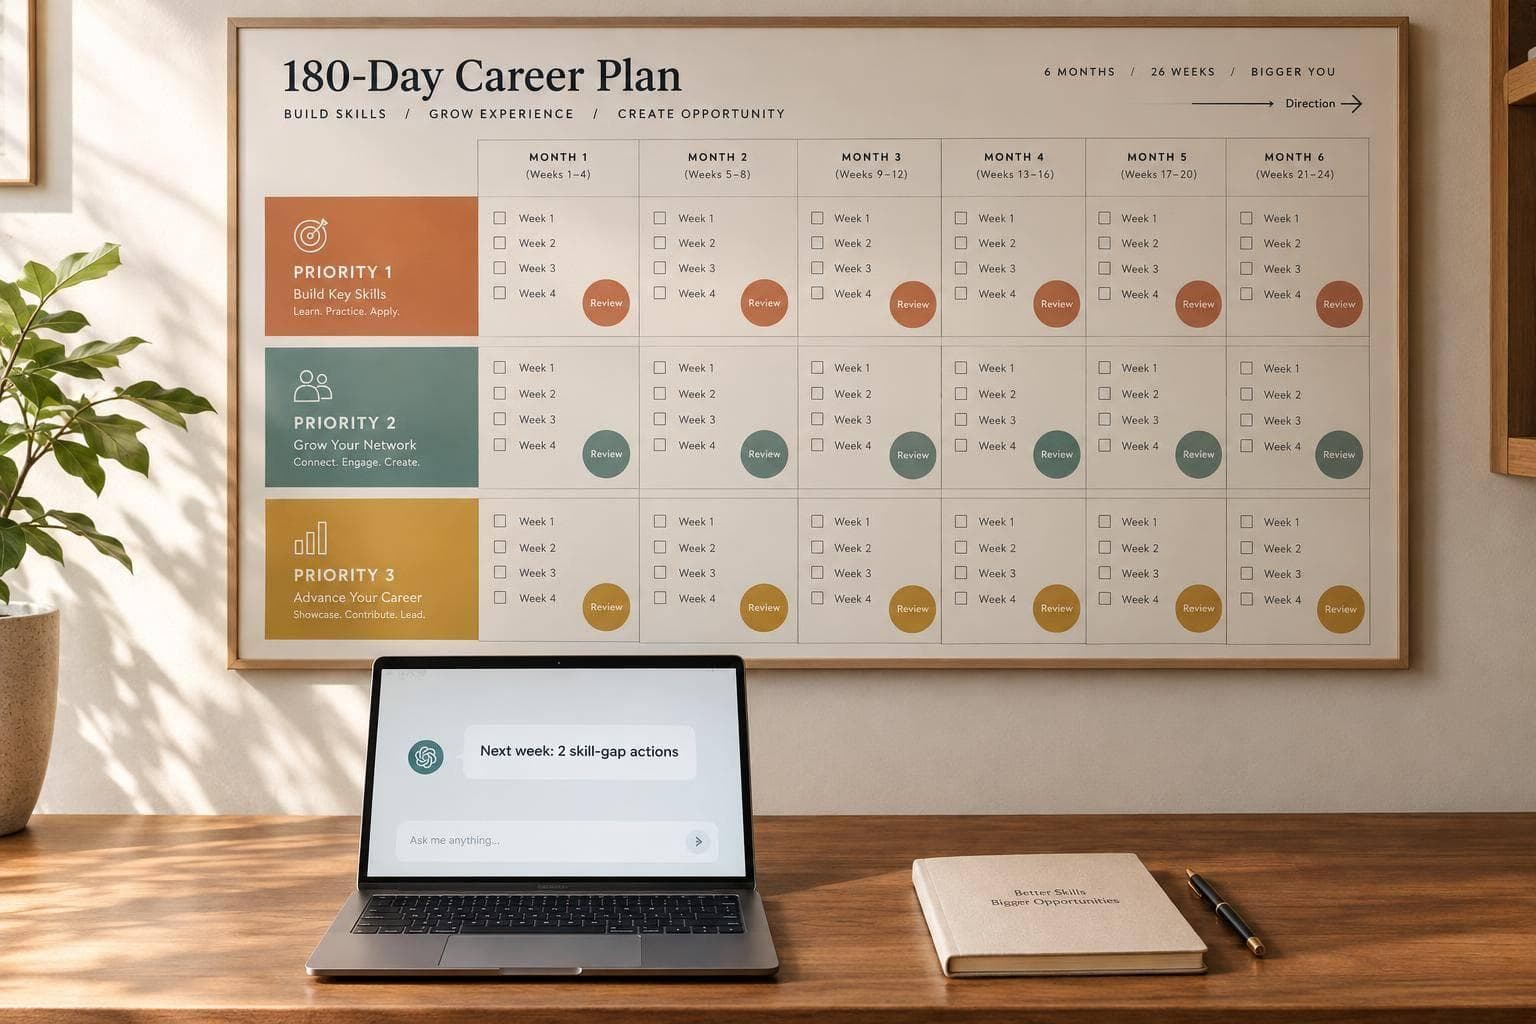
How to Use AI to Build a 180-Day Career Plan
Learn how AI helps structure a 180-day career plan with 3 priorities, skill gaps, weekly actions, and monthly reviews while you choose your direction.
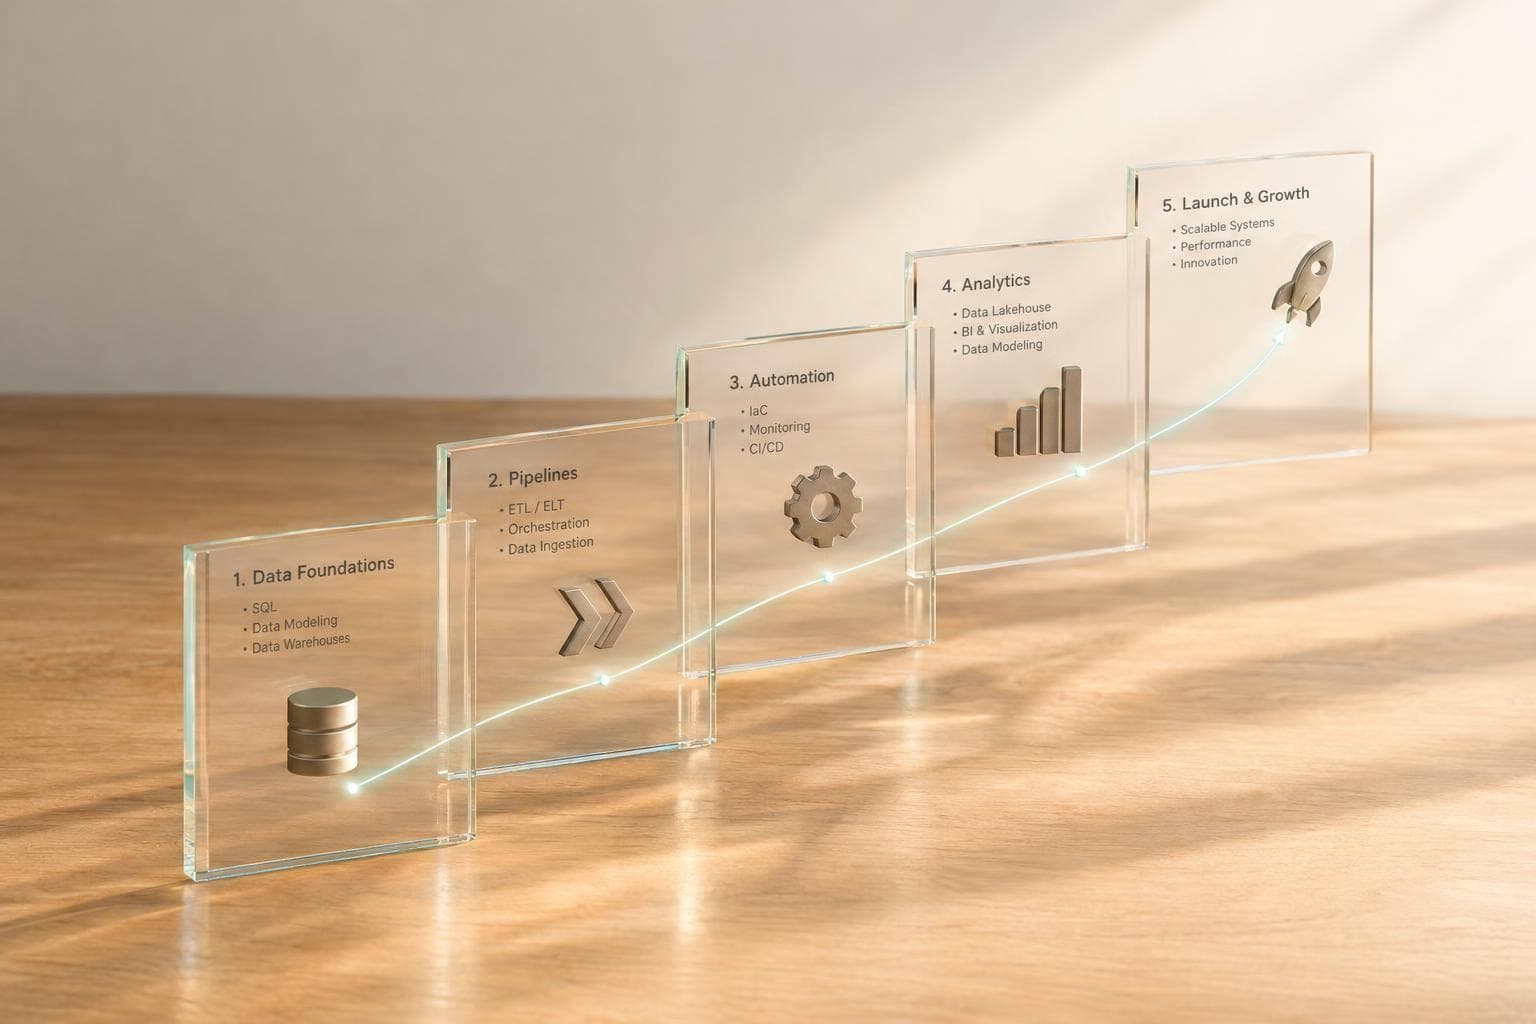
Data Engineer Roadmap
Explore a practical Data Engineer Roadmap by stage, skill, and project. Tailor your path by level, focus area, and learning pace.
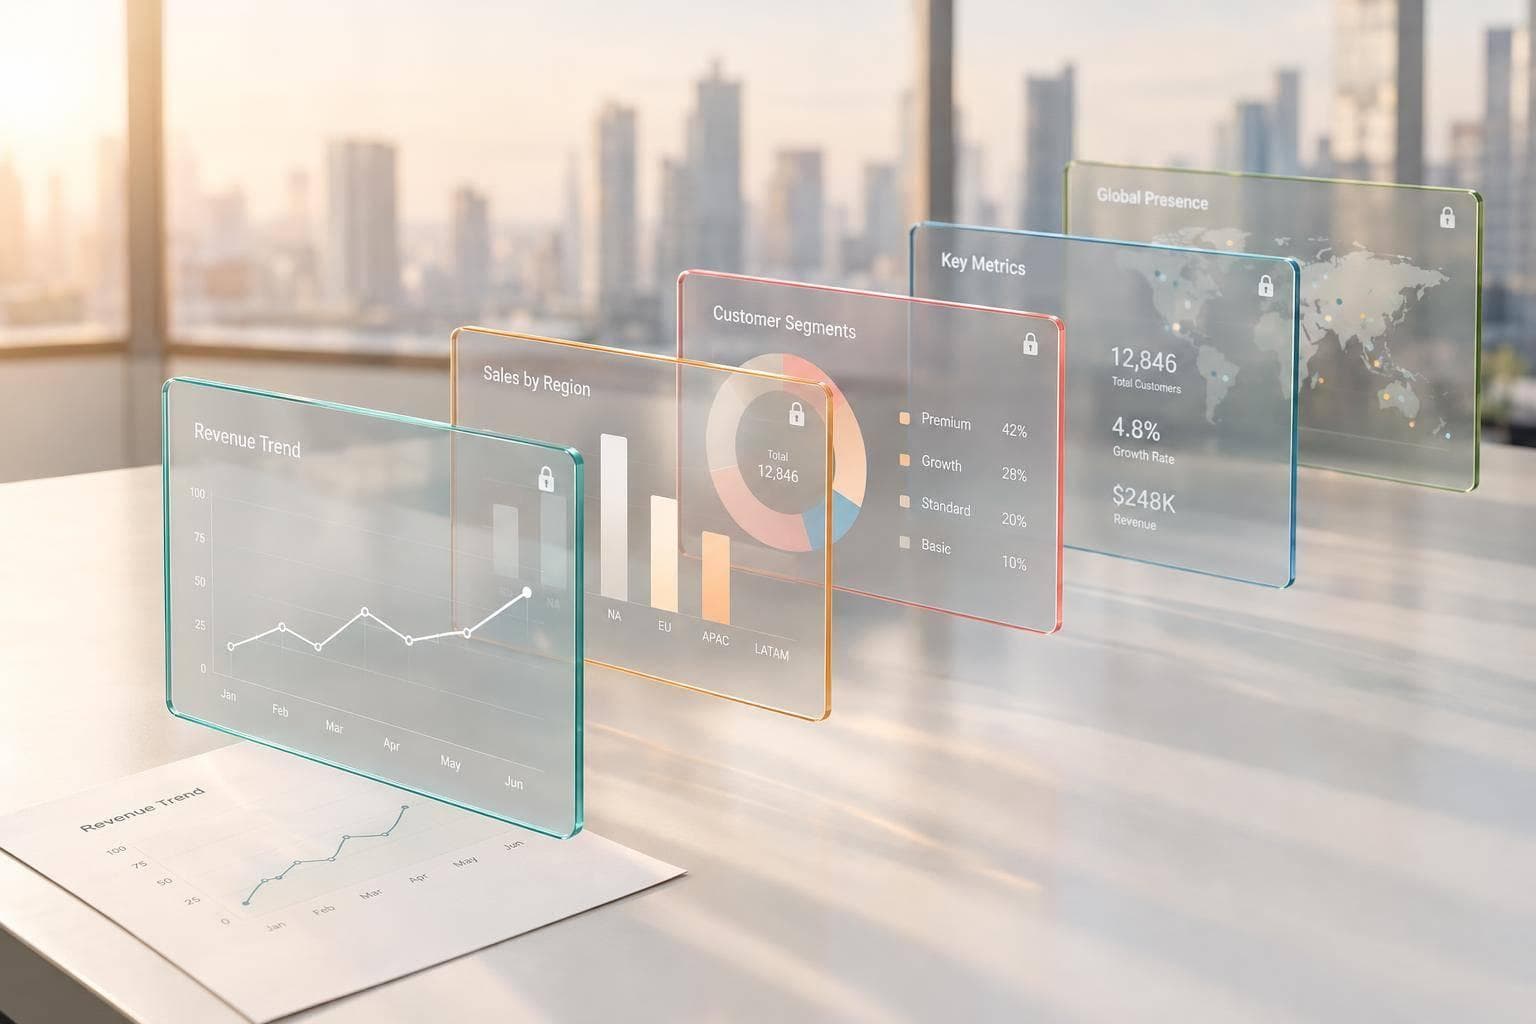
White-Label Embedded Analytics: Guide 2026
How to build secure, branded embedded analytics with tenant isolation, scoped embeds, exports, and staged rollout.
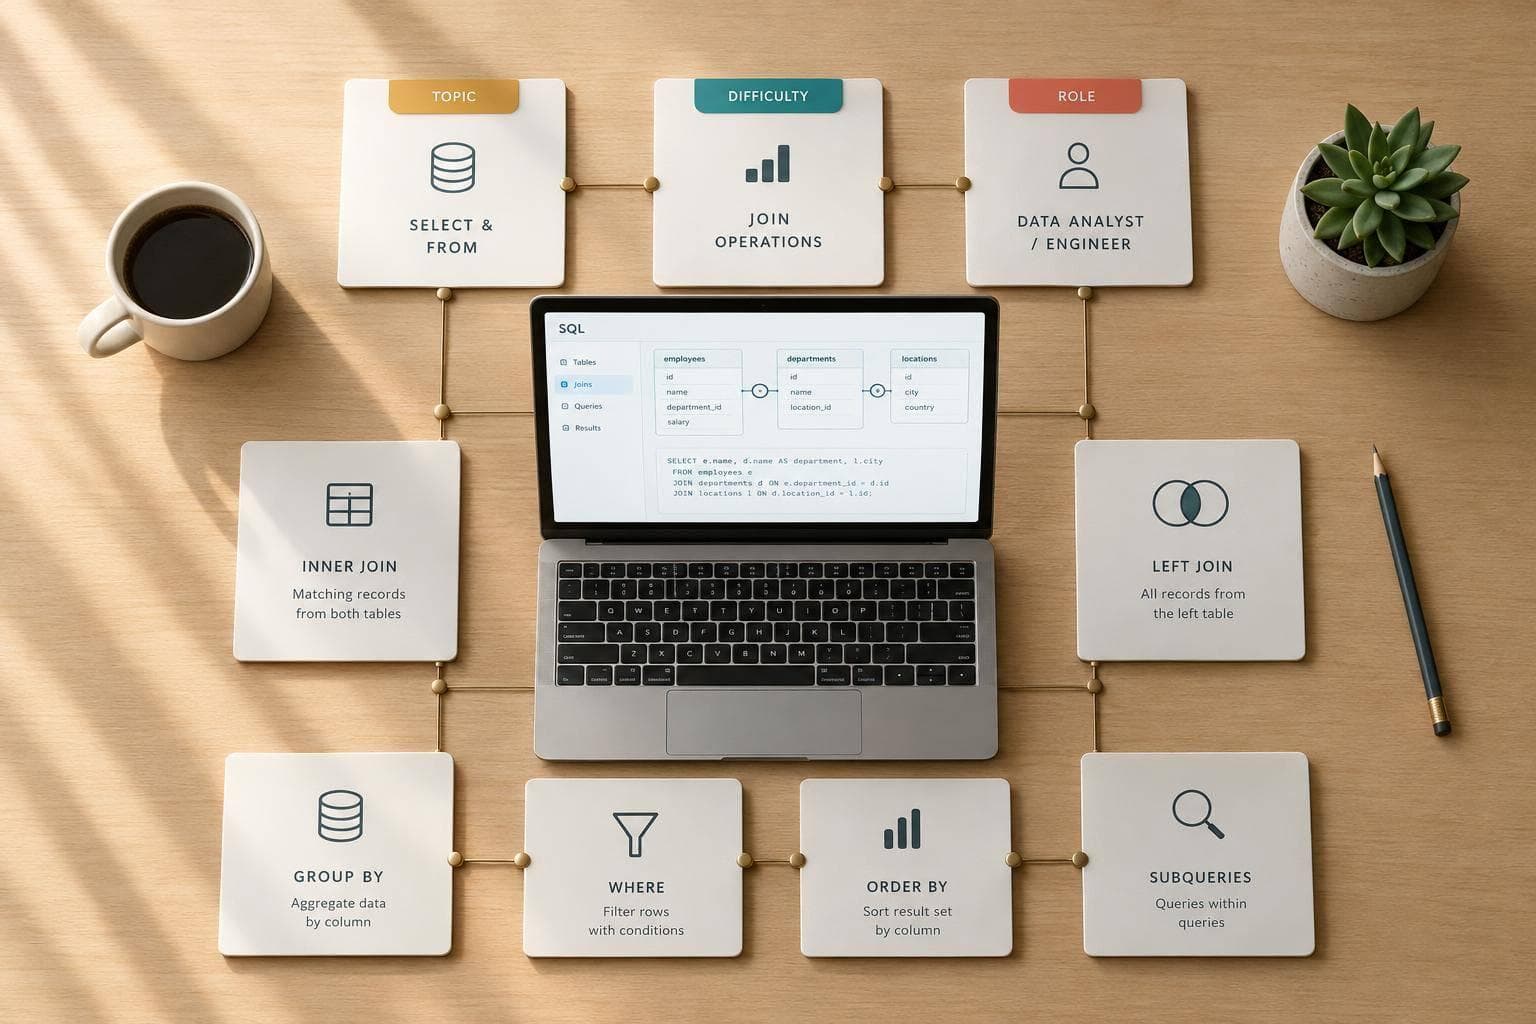
SQL Interview Questions
Practice SQL interview questions by topic, difficulty, and role with sample answers, explanations, and realistic variations.