Etl
44 articles tagged with "Etl"
Stateful Stream Aggregations: Core Concepts
Keys, windows, watermarks, triggers, and checkpoints for robust stateful stream aggregations in Spark and similar engines.
Airflow max_active_runs vs Pools
Serialize DAG runs with max_active_runs and throttle shared-resource tasks with pools, using both for correctness and capacity.
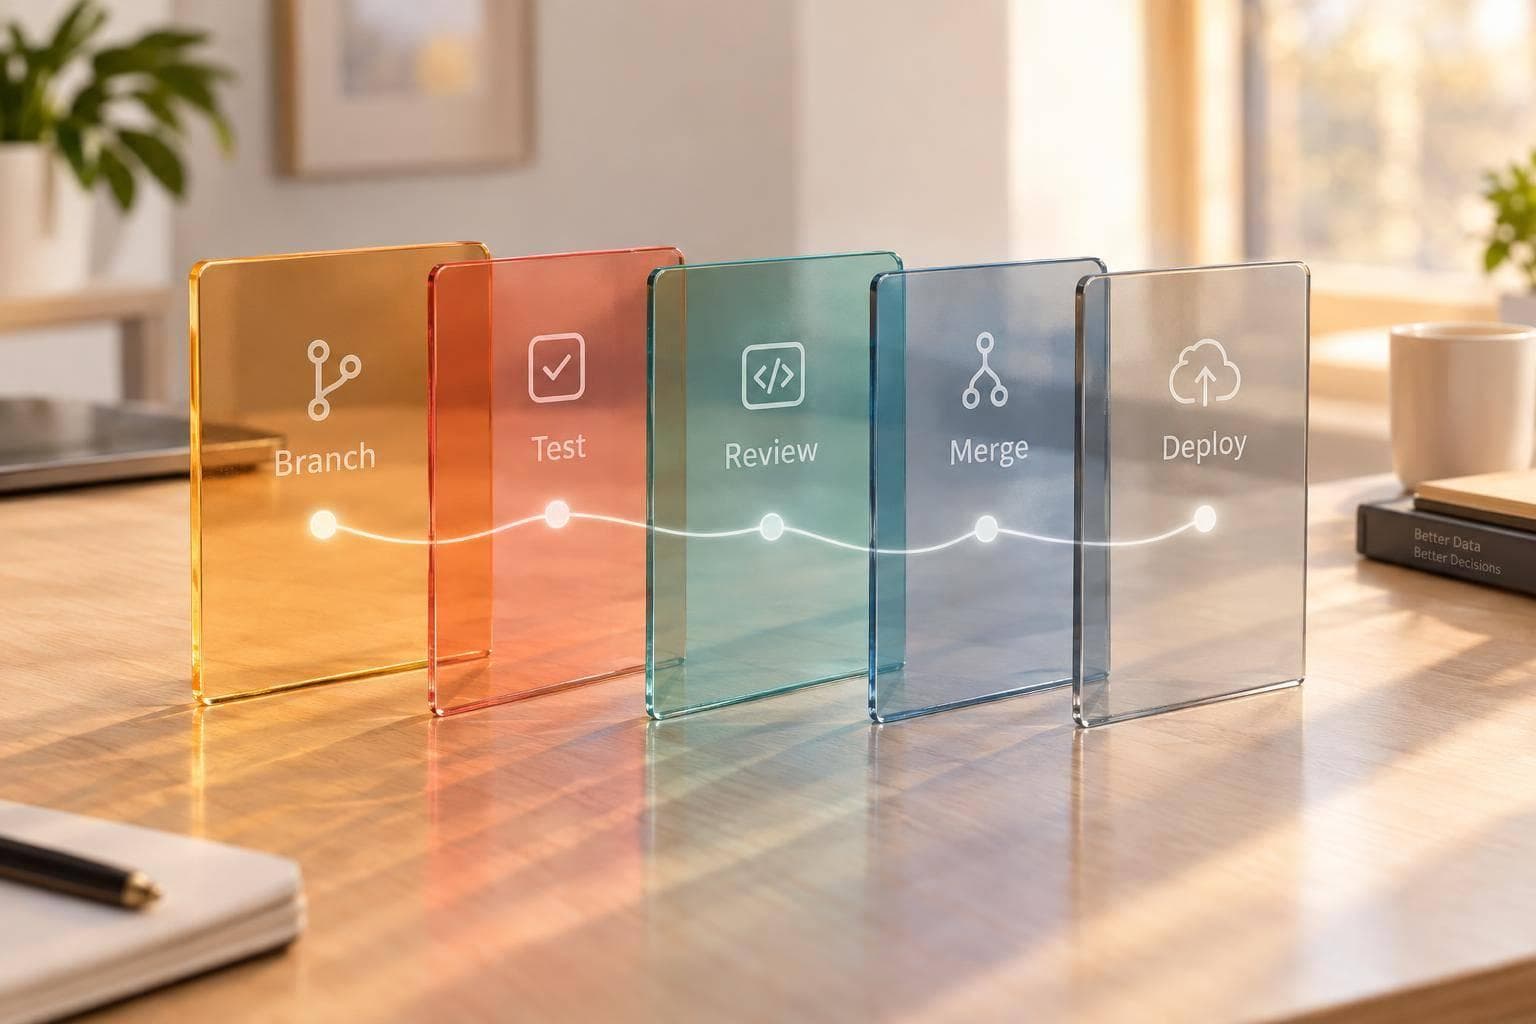
Version Control Basics for dbt Projects
Branch, test, review, merge, and deploy dbt changes with focused commits, CI validation, protected branches, and rollback plans.
Introduction to Stream Processing Frameworks
Compare Flink, Kafka Streams, Spark, and Beam; test correctness, latency, recovery, and cost before choosing a streaming framework.
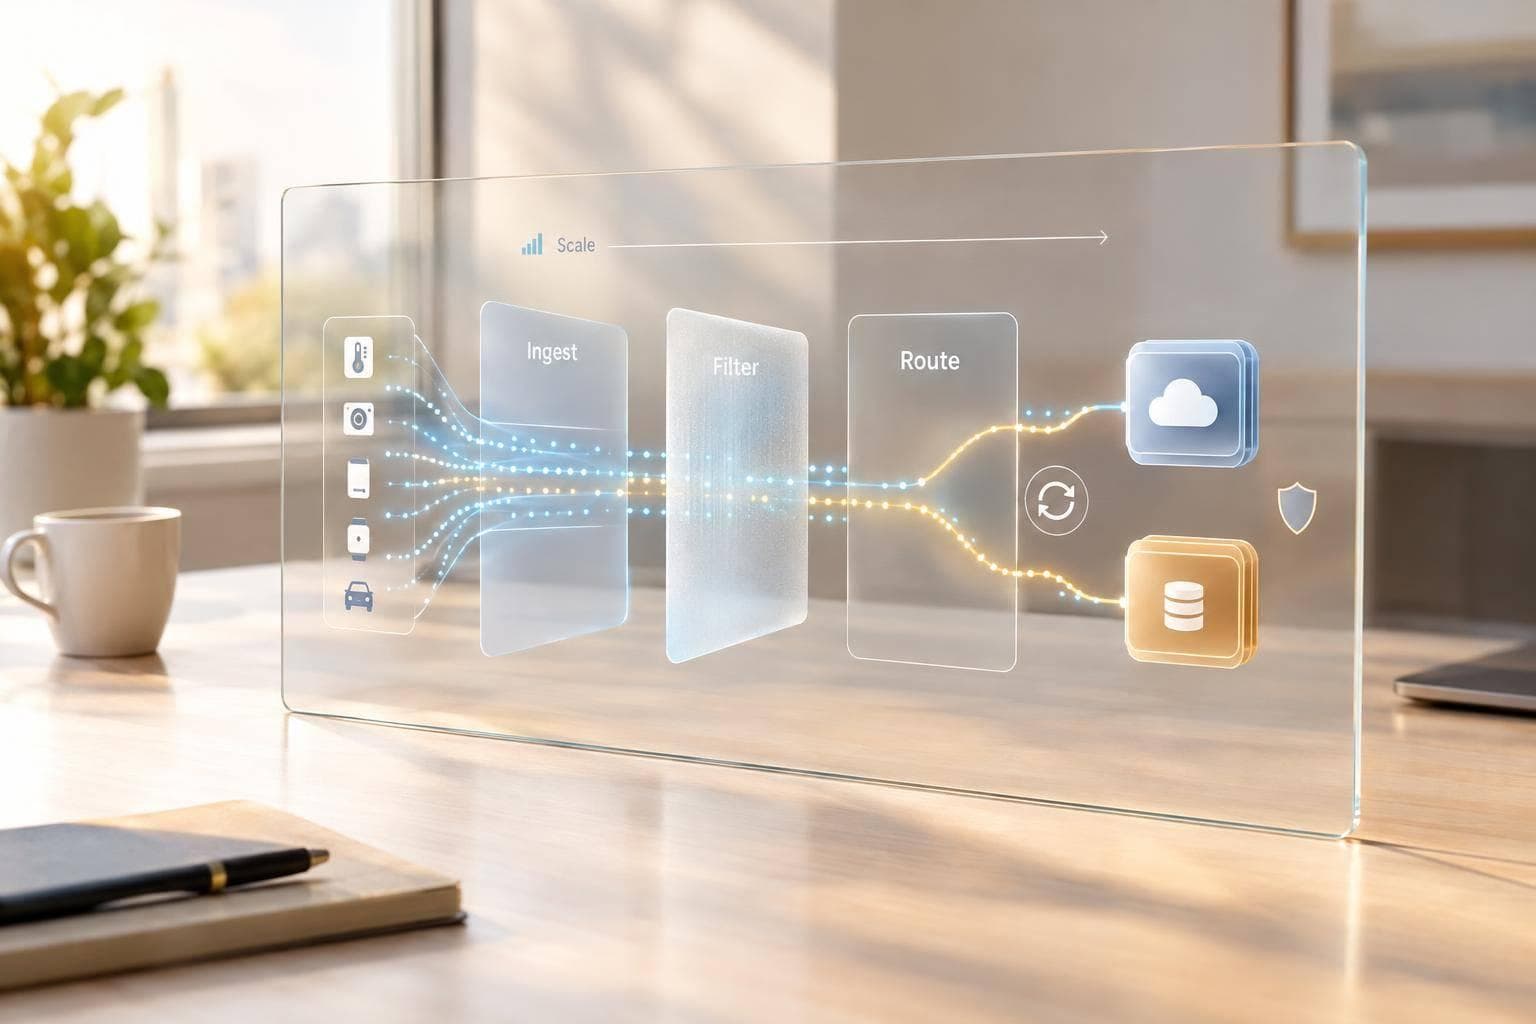
How AWS IoT Core Processes IoT Event Streams
Explains how IoT Core ingests, filters, and routes device events, plus guidance on scaling, replay, and reliability.
Airflow DAGs: Core Concepts and Task Design
Design Airflow DAGs for safe retries and idempotent publishing: task boundaries, sensors, schedules, timeouts, and testing.
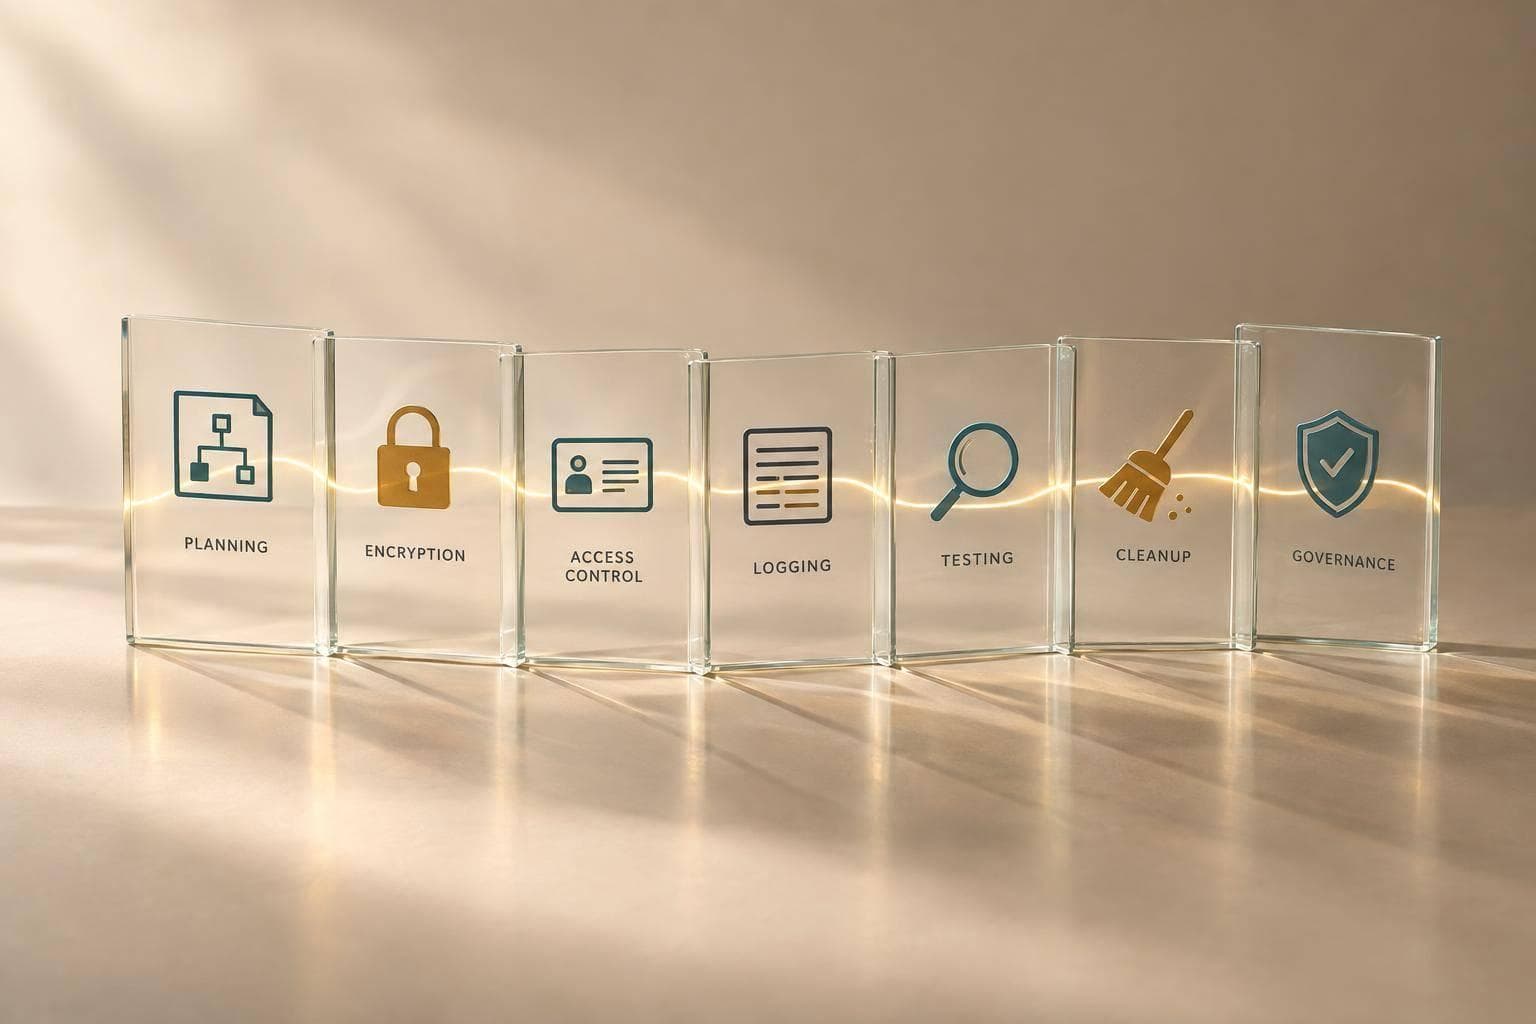
Security and Compliance in Data Migration
Checklist for secure data migration: planning, encryption, access controls, logging, testing, cleanup, and post-move governance.
12 ClickHouse Architecture Interview Questions
Guide to ClickHouse architecture: columnar storage, MergeTree parts, partitions, shards, replicas, Distributed tables, and query flow.
How to Build AI Streams with Kafka and Flink
Low-latency AI streams: use Kafka to ingest, Flink to build features and score, with replay, lateness handling, and exactly-once delivery.
7 Signs Python Pipelines Need Performance Profiling
Seven practical signals that reveal when your Python data pipeline needs profiling to find code, orchestration, or infrastructure bottlenecks.
Serverless Allocation Models For ETL And AI Workloads
Match serverless settings to each workload's tightest limit: latency for inference, throughput for ETL, dbt warehouse, joins for features.
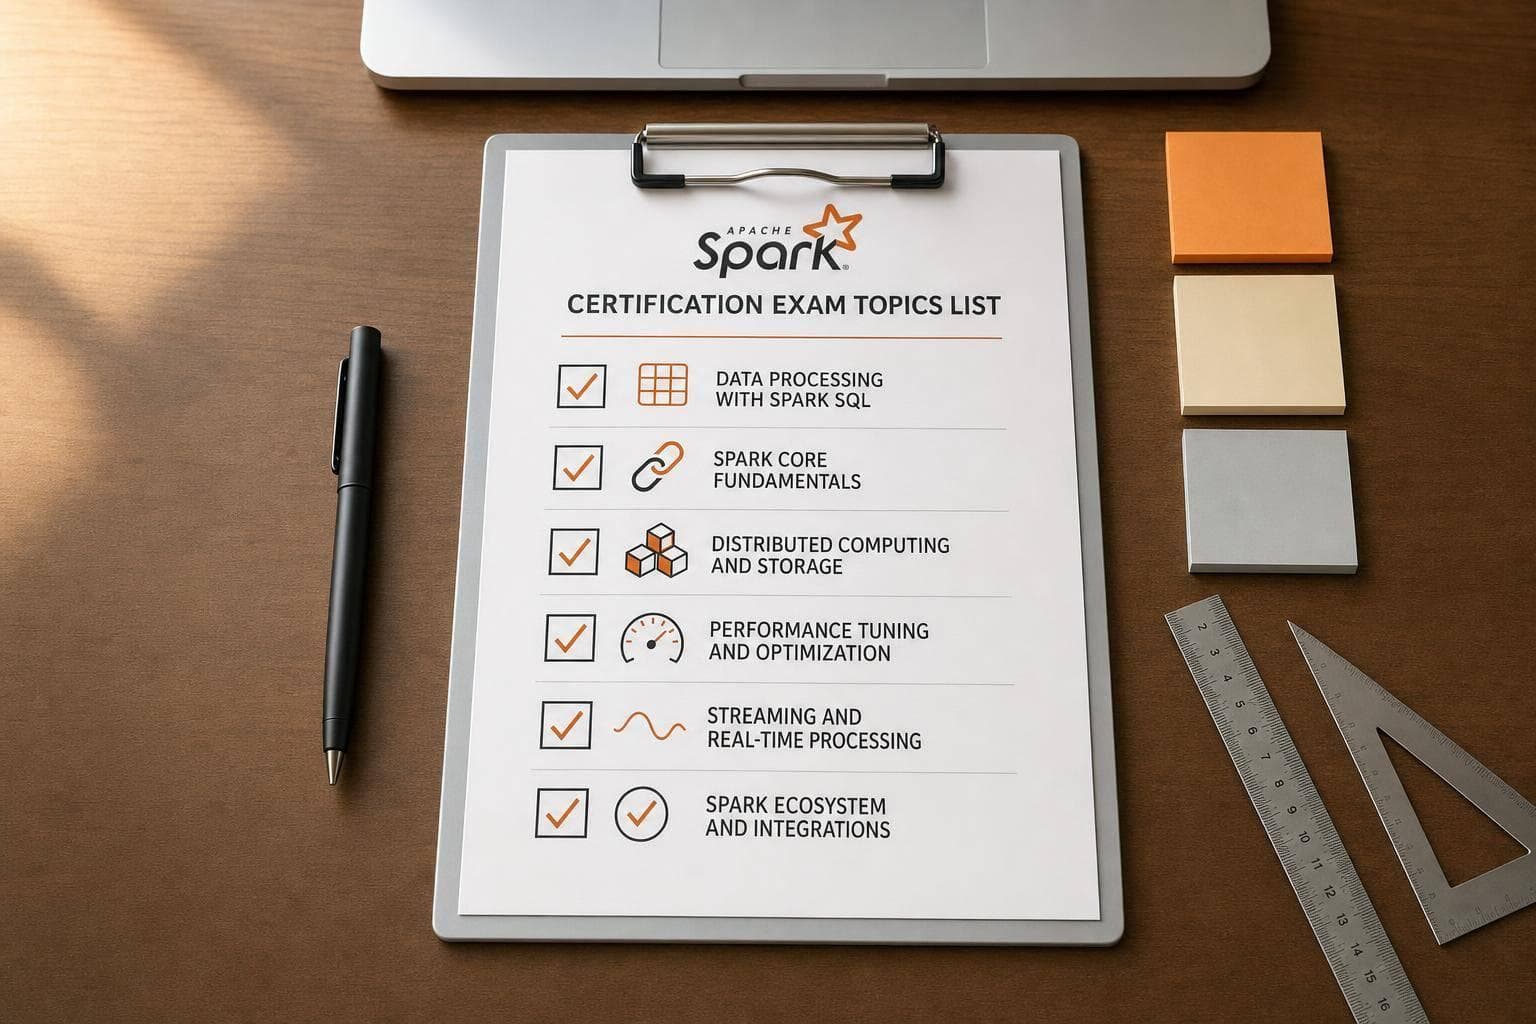
Apache Spark Certification Exam Topics List
Checklist of Spark exam essentials: DataFrames/SQL, joins, partitions, performance, streaming, and testing for hands-on prep.