Data Engineering
99 articles in "Data Engineering"
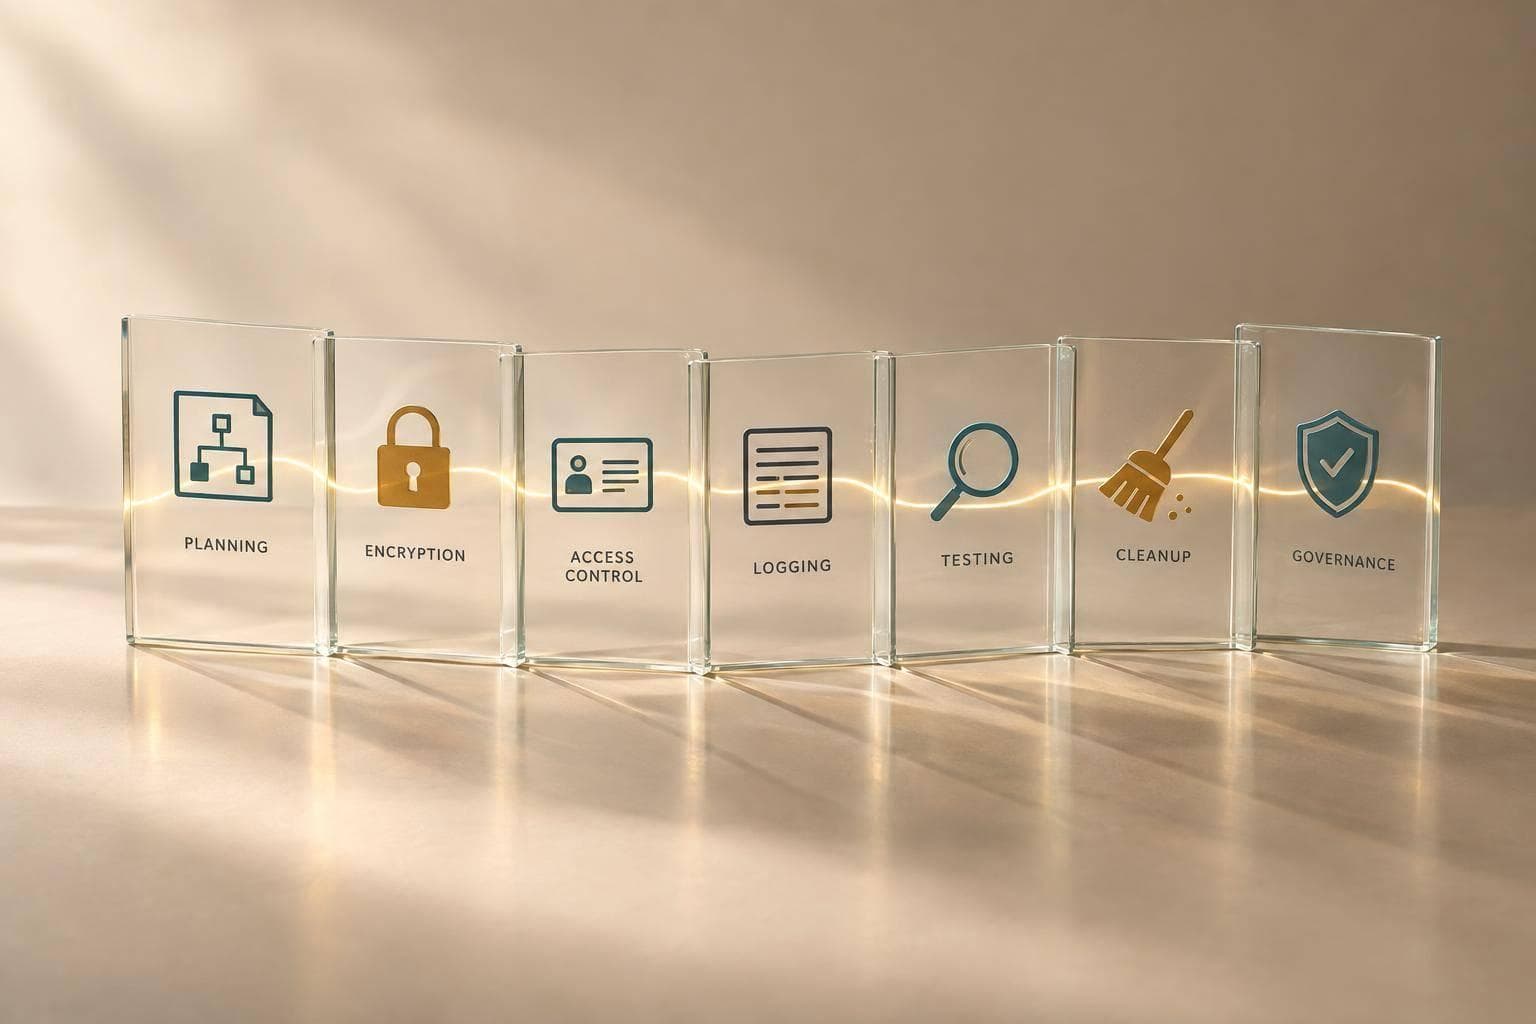
Security and Compliance in Data Migration
Checklist for secure data migration: planning, encryption, access controls, logging, testing, cleanup, and post-move governance.
Securing Event-Driven Architecture: Best Practices
Checklist to secure event-driven systems: map flows, enforce least privilege, validate schemas, protect identities, control retries, and audit.
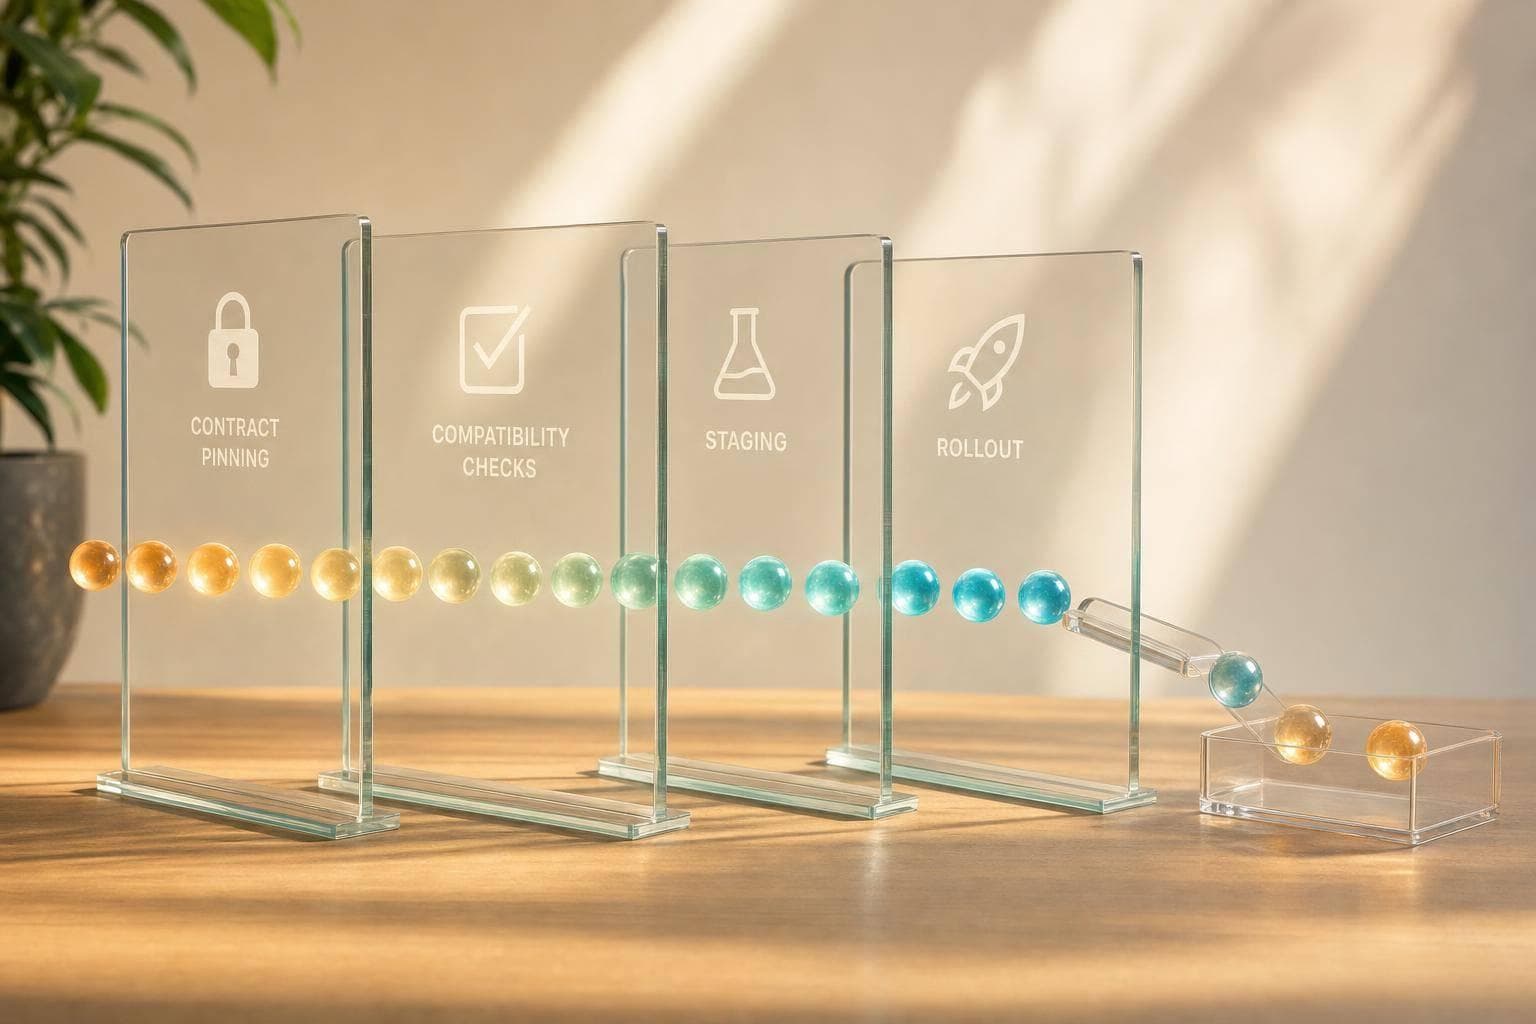
Handling Schema Drift in Event Streams
Prevent and contain schema drift in event streams: pin contracts, run compatibility and staging tests, use DLQs and staged rollouts.
12 ClickHouse Architecture Interview Questions
Guide to ClickHouse architecture: columnar storage, MergeTree parts, partitions, shards, replicas, Distributed tables, and query flow.
7 Signs Python Pipelines Need Performance Profiling
Seven practical signals that reveal when your Python data pipeline needs profiling to find code, orchestration, or infrastructure bottlenecks.
Serverless Allocation Models For ETL And AI Workloads
Match serverless settings to each workload's tightest limit: latency for inference, throughput for ETL, dbt warehouse, joins for features.
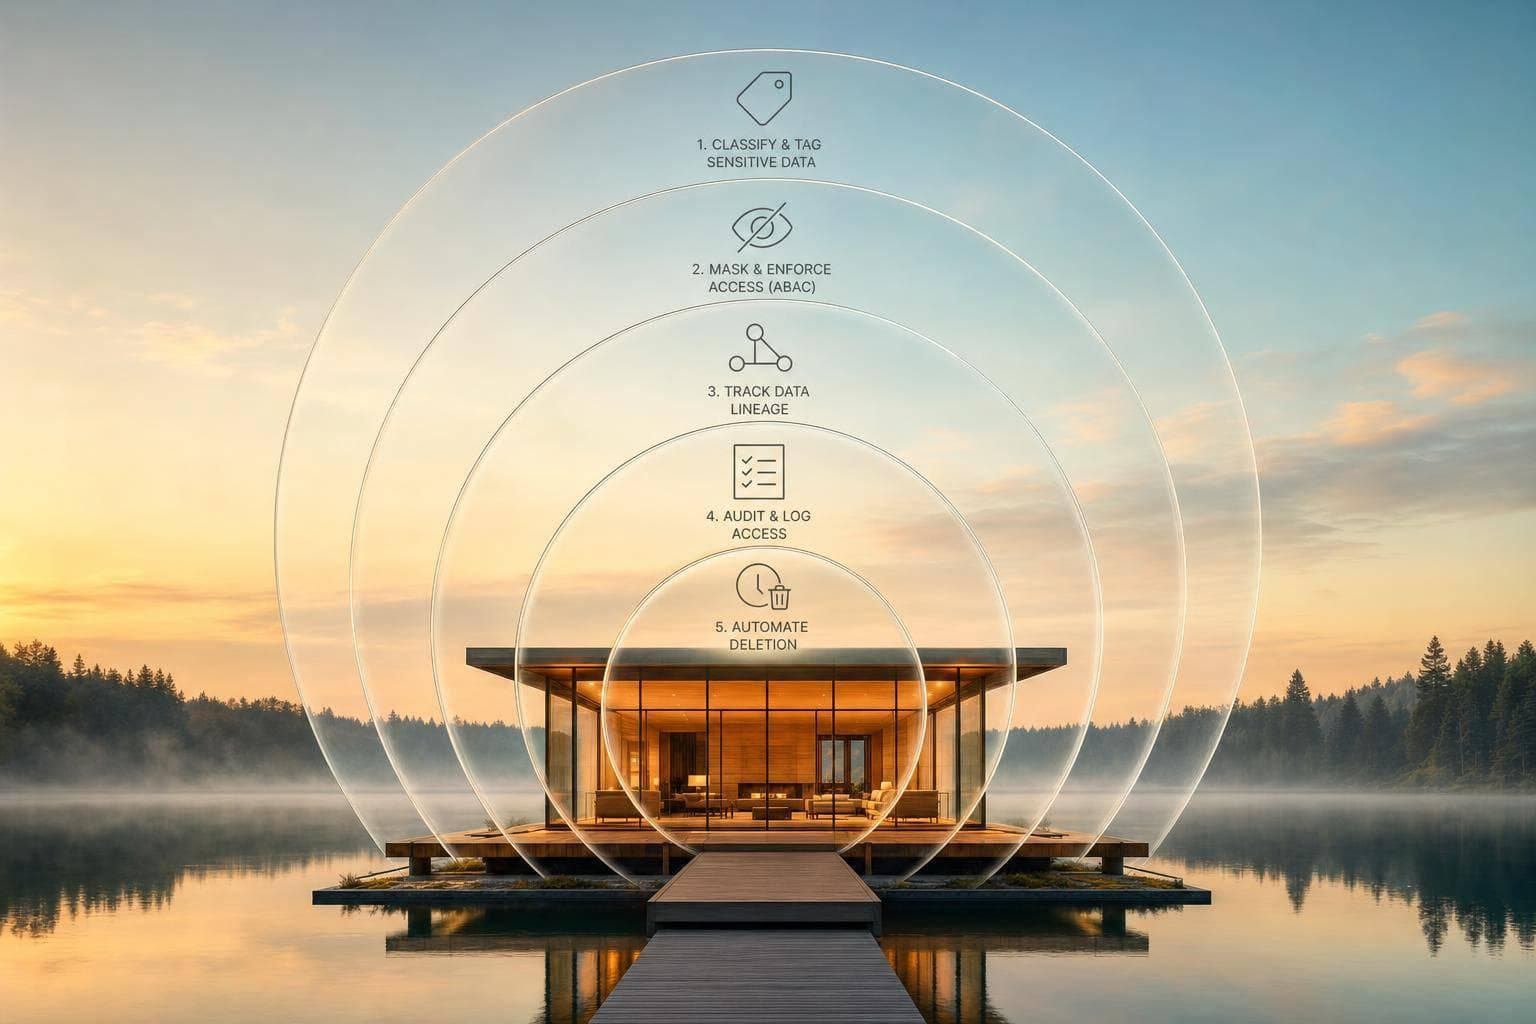
Lakehouse Governance for PII: Best Practices
Layered lakehouse PII controls: column tags, catalog-driven masking/ABAC, lineage, audit logs, and automated deletion.
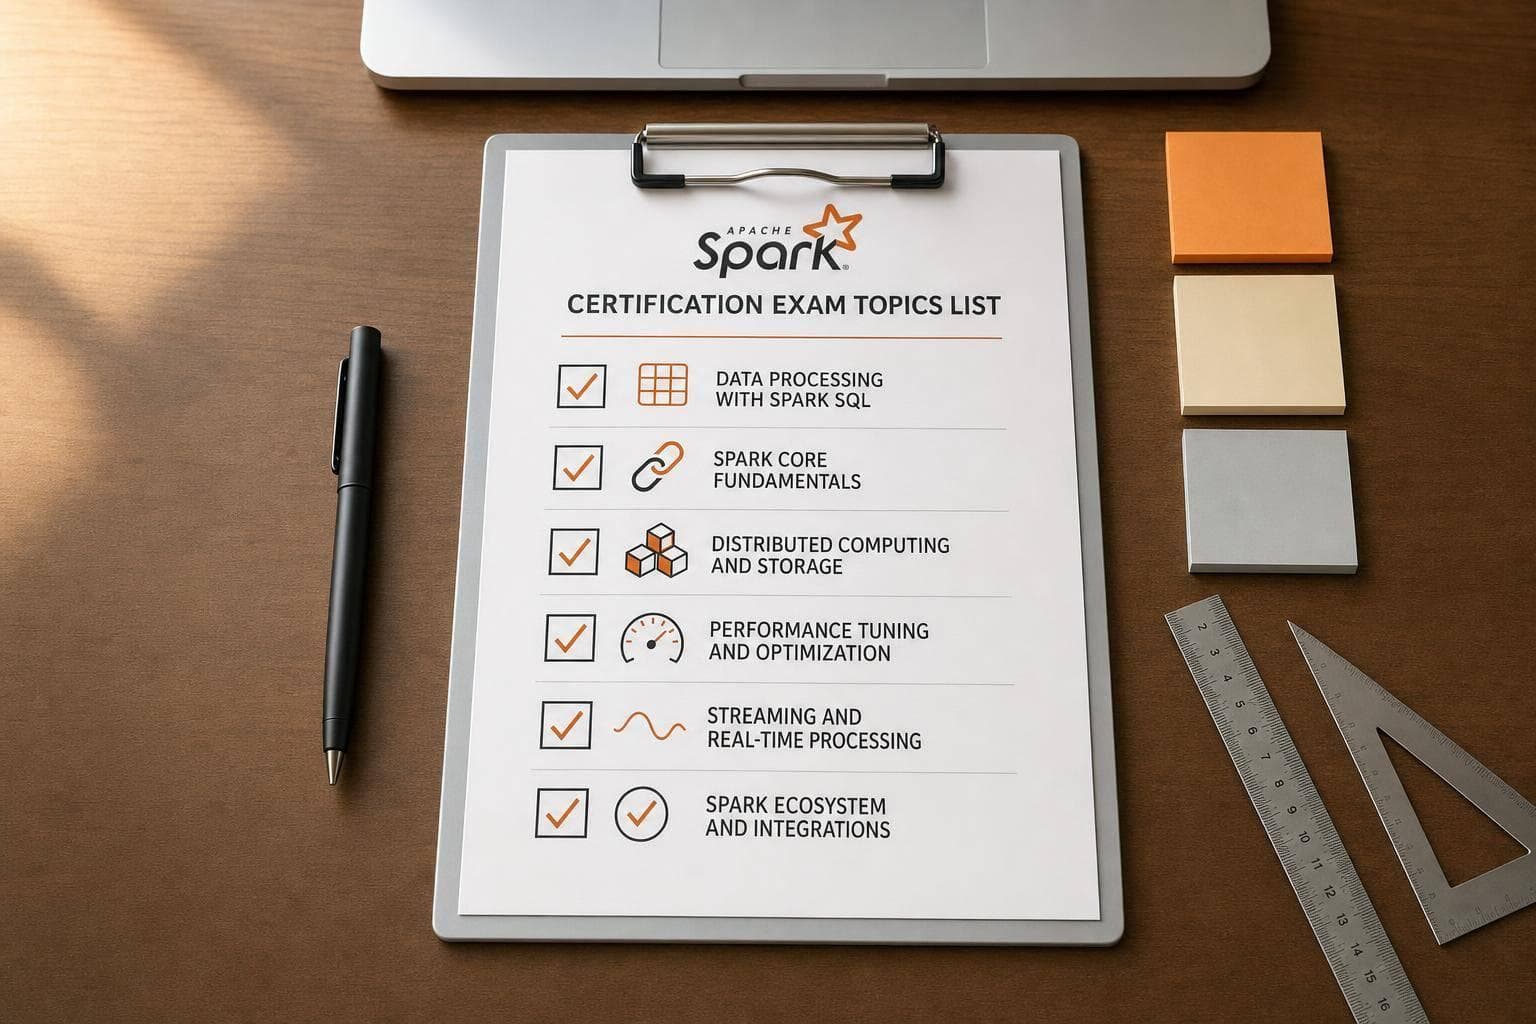
Apache Spark Certification Exam Topics List
Checklist of Spark exam essentials: DataFrames/SQL, joins, partitions, performance, streaming, and testing for hands-on prep.
What Makes Great Analytics Pull Requests
Keep analytics PRs small: state the change and impact, list affected metrics/models, and attach tests/screenshots for fast, accurate reviews.
Presto vs Trino Interview Questions
Explains the PrestoDB vs Trino split, rename, shared architecture, deployment differences, and interview-focused workload guidance.
30 Snowflake Interview Questions for Data Engineers
Core Snowflake interview topics: architecture, warehouses, recovery, loading, and security — emphasize trade-offs in cost, speed, and risk.
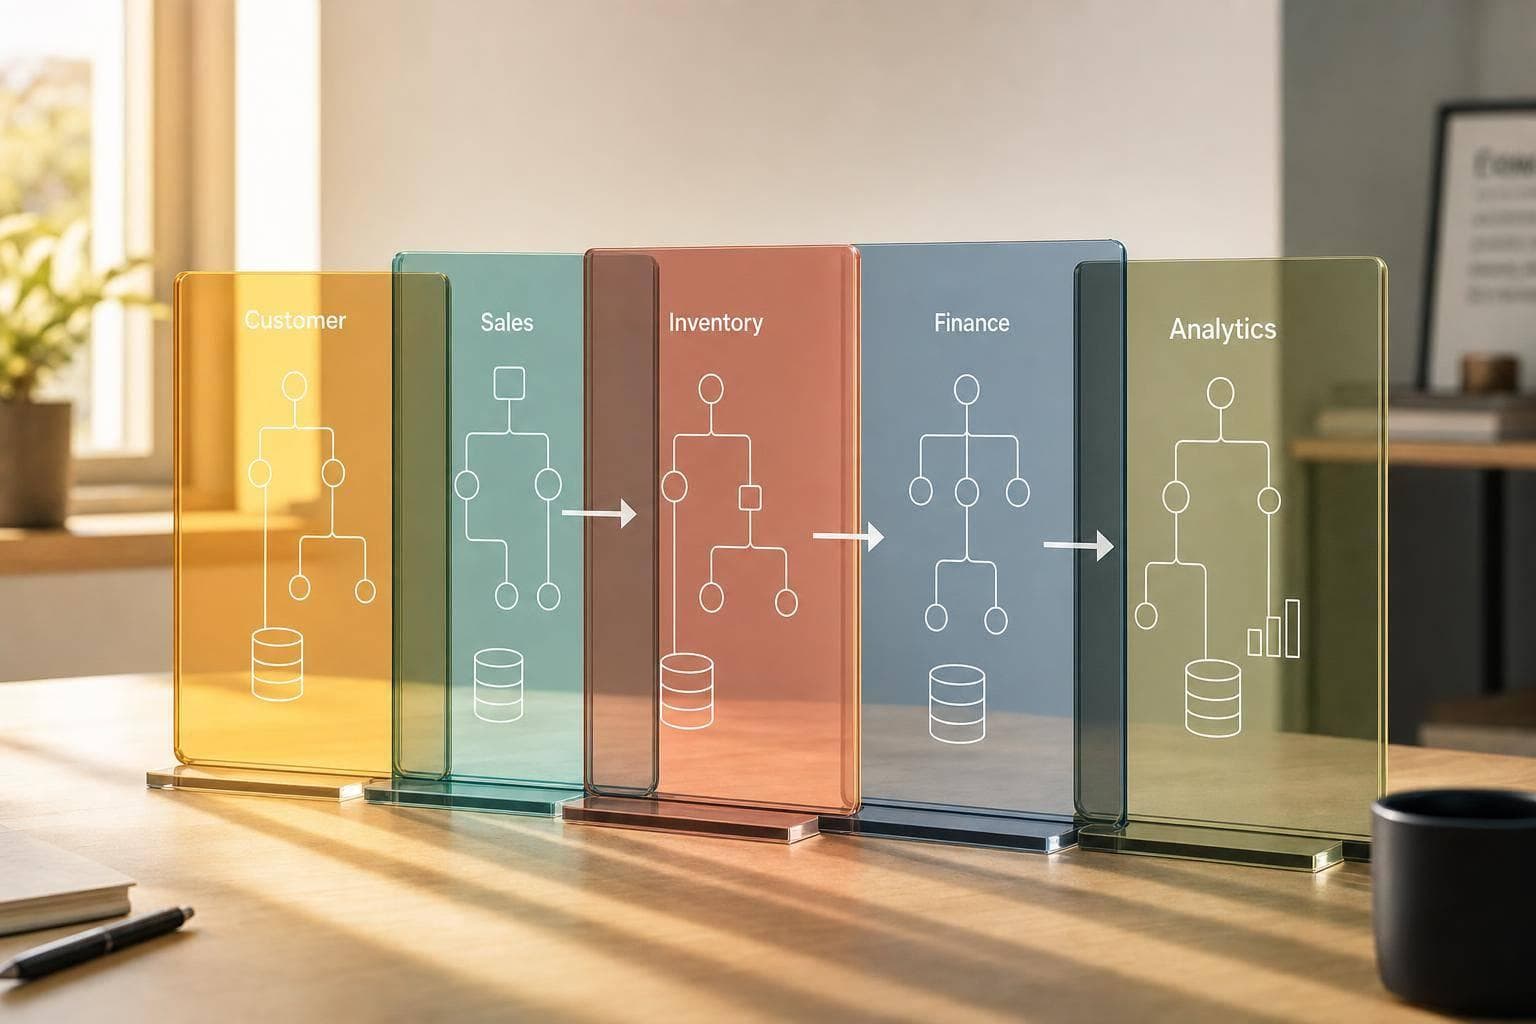
How to Use Context Mapping for Data Architecture
Map bounded contexts, classify relationships, and choose integration patterns to reduce rework, schema drift, and pipeline breakage.